

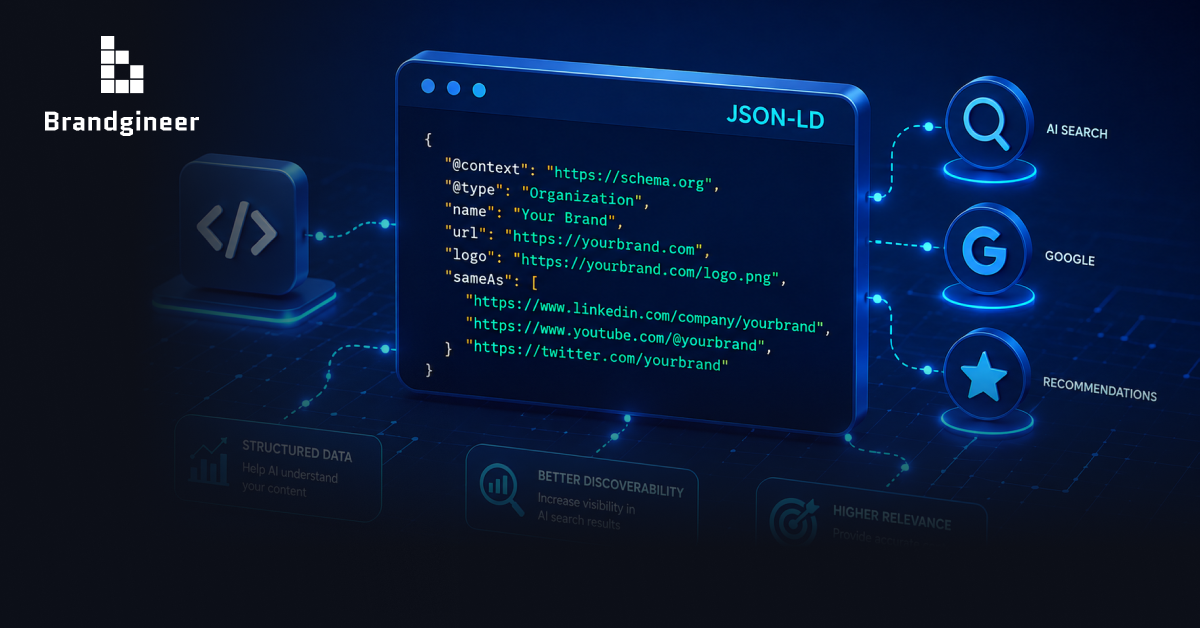
Schema markup does not earn AI citations on its own. But without it, AI has to guess what your content is, and retrieval systems rarely prioritise things they cannot classify with confidence. This guide covers what the evidence actually shows, the four schema types worth implementing with full JSON-LD examples, and the mistakes that make your schema invisible to AI crawlers.
Key Takeaways
- A 2026 Ahrefs study of 1,885 pages that added JSON-LD found no meaningful citation lift against matched controls. The widely repeated “schema triples your citations” figure has no original research behind it.1
- Princeton’s GEO research found structured data combined with authoritative citations and specific statistics produced citation rates up to 40% higher. The effect came from the combination, not from schema alone.
- The correct conclusion: schema is infrastructure for machine readability and entity resolution, not a tactic for getting cited.
- The most common and most damaging failure is schema injected by JavaScript, which makes it invisible to most AI crawlers.
- Organization schema with sameAs is the most frequently skipped type and the one with the highest long-term value, because it is the foundation of entity signals.
What Schema Markup Actually Does
Schema markup is JSON-LD code placed in the <head> of your page that declares to machines what type of content this is, who wrote it, when, and which entities it relates to.
This is the point most often misunderstood. Schema is not a quality signal, not a vote, not a ranking factor. It is descriptive metadata.
With schema, those questions are answered explicitly. You are not persuading AI that your content is good. You are making sure it understands what the content is.
This distinction matters because it sets your expectations. If you implement schema expecting citation rate to jump within a month, you will be disappointed. If you implement schema as the groundwork that stops your later content and entity work from being misread, you are using the right tool for the right job.
What the Evidence Says About Schema and AI Citations
The current evidence is mixed, and anyone stating a confident conclusion in either direction is running ahead of the data.
This is where most published advice on schema gets it wrong. The most repeated figure is that “pages with schema are cited 3x more often.” No original study supports that number. It appeared on several SEO blogs and was cross-cited between them until it started to look like an established fact.
The evidence against
Ahrefs published a 2026 study of 1,885 pages that added JSON-LD, compared against matched controls. The result: no meaningful citation lift across Google AI Overviews, AI Mode, or ChatGPT. Google AI Overviews were actually down 4.6%, and that decline was statistically significant. AI Mode was up 2.4% and ChatGPT up 2.2%, neither statistically significant.1
The evidence for
Princeton’s research on Generative Engine Optimization found that combining three elements, authoritative citations, specific statistics, and structured data, produced citation rates in AI answers up to 40% higher. The key detail: this is a combined effect. The study did not isolate the contribution of structured data on its own.1
How to read both results together
They do not contradict each other. Ahrefs measured the effect of adding schema to existing content with everything else held constant. Princeton measured the effect of a bundle of changes in which schema was one component. The reasonable conclusion: schema alone does not move citations, but it is part of a content configuration that works.
This leads to an important practical implication: if your technical budget is limited, do not spend all of it on schema and stop there. Schema should be a one-time job, done correctly, after which you move to the harder work of content quality and entity signals. Inverting that priority order is a common mistake among technical teams.
Why to implement it anyway
Three reasons hold even if the direct citation effect is zero:
First, low cost and zero risk. Schema is static code, written once, with no effect on design and no effect on load speed when implemented correctly.
Second, Organization schema with sameAs is the only way to declare your entity in machine-readable form. There is no substitute. This is not about short-term citations but about giving AI systems a basis for consolidating scattered signals about your brand into a single entity.
Third, FAQPage and HowTo split content into independent units. AI retrieval systems operate on passages, not whole pages. Splitting the content yourself means you control how it gets divided rather than leaving that to an algorithm.
The Four Schema Types Worth Implementing
1. Article
Use for all editorial content: blog posts, guides, analysis, news.
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "Article title, maximum 110 characters",
  "description": "One or two sentence summary stating what question this article answers",
  "author": {
    "@type": "Person",
    "name": "Author name",
    "jobTitle": "Job title",
    "worksFor": {
      "@type": "Organization",
      "name": "Company name",
      "url": "https://example.com"
    }
  },
  "publisher": {
    "@type": "Organization",
    "name": "Company name",
    "url": "https://example.com"
  },
  "datePublished": "2026-08-12",
  "dateModified": "2026-08-12",
  "inLanguage": "en",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://example.com/article-url/"
  }
}
What to watch: author should be a Person with worksFor, not just an Organization. A named author with a specific job title creates a clearer expertise signal for systems assessing credibility. The dateModified field must genuinely update every time you edit the content. Leaving dateModified equal to datePublished for two years is declaring that your content is stale.
2. FAQPage
Use for any content with a question and answer structure.
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [
    {
      "@type": "Question",
      "name": "The question phrased exactly as a user would type it into an AI engine",
      "acceptedAnswer": {
        "@type": "Answer",
        "text": "A self-contained answer, maximum two sentences, including at least one specific number or named entity, answering fully in the first sentence."
      }
    },
    {
      "@type": "Question",
      "name": "Second question",
      "acceptedAnswer": {
        "@type": "Answer",
        "text": "Second answer, which must also stand alone if separated from the article context."
      }
    }
  ]
}
The rule for writing acceptedAnswer: every answer must stand alone. Assume AI will lift that exact text out of your article and drop it into a completely different context. If it becomes meaningless when separated, or begins with “As mentioned above,” it is not usable.
On Google narrowing FAQ rich results: it is true that the display value on traditional search results has dropped considerably. But that is an SEO reason, not an AEO reason. For AEO, the value of FAQPage is that it splits content into exactly the units retrieval systems work with. This is the clearest illustration of the principle: schema serves machine reading, not display.
3. HowTo
Use for step-by-step instructional content.
{
  "@context": "https://schema.org",
  "@type": "HowTo",
  "name": "Process name",
  "description": "Brief description of what problem this process solves",
  "step": [
    {
      "@type": "HowToStep",
      "name": "Step 1 name",
      "text": "Step 1 described in enough detail to be actioned without reading the other steps."
    },
    {
      "@type": "HowToStep",
      "name": "Step 2 name",
      "text": "Step 2, also self-contained."
    }
  ]
}
What to watch: AI engines frequently cite a single step rather than the full process. Write each HowToStep as though it will appear alone. Avoid phrasing like “continue from the step above” or “same as step 2.”
4. Organization with sameAs
Place on the homepage and About page. This is the most frequently skipped schema type.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "Official company name",
  "url": "https://example.com",
  "logo": "https://example.com/logo.png",
  "description": "What the company does, for whom, and where",
  "foundingDate": "2020",
  "address": {
    "@type": "PostalAddress",
    "addressLocality": "Ho Chi Minh City",
    "addressCountry": "VN"
  },
  "sameAs": [
    "https://linkedin.com/company/company-name",
    "https://www.crunchbase.com/organization/company-name",
    "https://clutch.co/profile/company-name",
    "https://www.facebook.com/companyname"
  ]
}
Why sameAs matters more than it looks: AI models maintain entity graphs. When a system encounters your company name on LinkedIn, and on your own site, it needs to know those are the same organisation. sameAs says that explicitly. Without it, signals about your brand can fragment into several disconnected entities, none of them strong enough to be recognised.
Only list profiles you have verified and actually control. Listing a page abandoned in 2021 does not help and may signal an inactive organisation.
The Order to Implement Schema In
If you cannot do everything at once, the order below maximises early results for the least effort.
Why order matters: the four schema types are not equally valuable, and some only pay off once another is in place. For a real deployment across an insights or blog section, this sequence makes sense:
1. Organization with sameAs on the homepage, first. This is the root of the entity graph. McKinsey research found 85% of brand mentions in AI answers come from third-party sources, which makes explicitly declaring that those sources belong to one organisation the highest-leverage step.2 Without it, every Article schema below describes content belonging to an entity the AI has not resolved.
2. Article across the whole insights section, in bulk. Apply this via template rather than per post, so every new article gets schema automatically. Configure author as a Person with worksFor from the start, since retrofitting that across dozens of posts costs far more later.
3. FAQPage on posts that already have a question and answer structure. Only apply it where genuine Q&A content exists. Do not add FAQs to a post purely to justify the schema, since schema content must match visible content.
4. HowTo on instructional posts, last. Fewest posts qualify for HowTo, so leave it until the end. But where a post does qualify the value is high, since each step becomes its own citable unit.
A note on the order results arrive: homepages and service pages tend to get cited by AI before new blog posts, even when the blog posts are better optimised, because higher-level pages already carry accumulated linking signals. That reinforces the case for doing Organization schema first: it is the schema on the page most likely to produce early results.
Five Implementation Failures That Make Schema Invisible
This is the most important section of the guide. Broken schema is worse than no schema, because you believe a job is done when it is not.
Failure 1: Schema injected by JavaScript
This is the most serious and most common failure on sites built with modern frameworks.
If schema only appears after JavaScript executes, most AI crawlers will see nothing. Googlebot can render JavaScript, but crawlers from other AI engines do not always, and there is no public commitment that they will.
How to check: run curl -s https://your-site.com/page/ | grep “application/ld+json”. If nothing returns, your schema does not exist for any crawler that skips JavaScript.
How to fix: move to server-side rendering or static generation for the <head>. With Next.js, Nuxt, or Astro this is the default configuration. With a pure React or Vue SPA, you need a pre-render step.
Failure 2: dateModified never updates
Many CMS platforms set dateModified equal to datePublished at publication and never touch it again, even when content is edited.
The consequence: you update the statistics in an article from 2024 figures to 2026 figures, but the schema still declares the last edit as 2024. Systems that favour recent sources will file you under stale content.
How to fix: configure the CMS to update this field on save. If done manually, add it to the editorial process as a required step.
Failure 3: FAQPage content does not match visible content
Some teams put questions and answers into FAQPage schema that do not appear on the page at all, treating it as a way to stuff in extra content.
This is a risk. Google states explicitly that structured data must reflect content genuinely present on the page, and violations can trigger manual action. Beyond the policy risk there is a practical one: if AI cites an answer from your schema and the user clicks through and cannot find it, that experience works against you.
How to fix: keep schema FAQs matched to visible FAQs. If you do not want a long visible FAQ section, trim the schema rather than inventing content.
Failure 4: Missing Organization schema and sameAs
Many sites implement meticulous Article schema on every post but have no Organization schema on the homepage at all.
The result is that you have clearly declared every piece of content but never declared who you are. For AEO this is the most expensive omission long term, because entity recognition takes months to accumulate and you are denying the system a starting point.
Failure 5: Declaring the wrong schema type
Using Article for a service page, Product for a blog post, FAQPage for a page with no question and answer structure.
Declaring the wrong type is worse than declaring nothing, because it actively points systems in the wrong direction. Service pages should use Service, homepages should use Organization and WebSite, listings should use ItemList.
12-Step Implementation Checklist
Audit phase
Implementation phase
Verification phase
How to Verify Your Schema Actually Works
Three tools, three different purposes, and you need all three.
Google Rich Results Test checks whether your schema qualifies for Google’s special display formats. It is the fastest way to catch syntax errors, but it only checks schema types Google supports for display, not full validity.
Schema.org Validator checks validity against the schema.org standard itself, including types Google does not use. Use it to catch what Rich Results Test misses, such as non-existent fields or wrong data types.
Raw HTML inspection is the most important step for AEO and the one most often skipped. Both tools above render JavaScript, so they will report your schema as perfect even when a crawler that skips JavaScript sees nothing at all.
How to do it: run curl -s https://your-site.com/page/ | grep -A5 “ld+json”. If the schema appears, you are fine. If not, this is the problem to fix before anything else, because all the effort spent writing schema is not reaching where it needs to go.
How often to check: after every deploy that changes templates, and quarterly as routine. Schema is often silently disabled by CMS updates or theme changes with nobody noticing.
Frequently Asked Questions
Does schema markup actually help you get cited by AI?
The evidence is mixed. A 2026 Ahrefs study of 1,885 pages that added JSON-LD found no meaningful citation lift against matched controls. Princeton’s GEO research found structured data combined with authoritative citations and specific statistics produced citation rates up to 40% higher. Schema is a prerequisite for machine readability and entity resolution, not a standalone citation lever.
If schema does not directly increase citations, why implement it?
Three reasons: it lets AI identify content type instead of inferring it, Organization schema with sameAs is the only machine-readable way to declare your entity, and FAQPage and HowTo split content into the independent answer units retrieval systems work with. The cost is low and there is no downside risk.
Google removed FAQ rich results, so is FAQPage schema still worth it?
Yes, for a different reason. Its traditional SEO value dropped when Google narrowed FAQ snippet display. For AEO, FAQPage remains useful because it splits content into self-contained question and answer pairs, exactly the units AI retrieval systems process.
Does schema markup injected by JavaScript work?
It is high risk. Googlebot can render JavaScript but many other AI crawlers cannot. Check with curl -s [url] | grep “ld+json”. If nothing returns, your schema does not exist for those crawlers.
What is the most common schema markup mistake?
Schema injected by JavaScript, dateModified that never updates, FAQPage content that does not match visible content, missing Organization schema and sameAs, and declaring a schema type that does not match the actual content.
Want to know whether your site’s schema is actually working for AI crawlers? Book a consultation with Brandgineer →
Author
Written by Abbie, AEO Expert at Brandgineer | brandgineer.co
Optimised for AI visibility across ChatGPT, Google AI Overviews, and Perplexity.
Read next: The 5-step guide to increasing AI visibility | How to measure AI visibility
Data Sources
- Schema Markup and AI Citations: What the Data Actually Shows (2026). fSEO, summarising Ahrefs (1,885 pages) and Princeton GEO research. https://fractionalseo.services/blog/schema-markup-ai-citations-data/
↩︎ - New Front Door to the Internet: Winning in the Age of AI Search. McKinsey & Company. https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/new-front-door-to-the-internet-winning-in-the-age-of-ai-search
↩︎